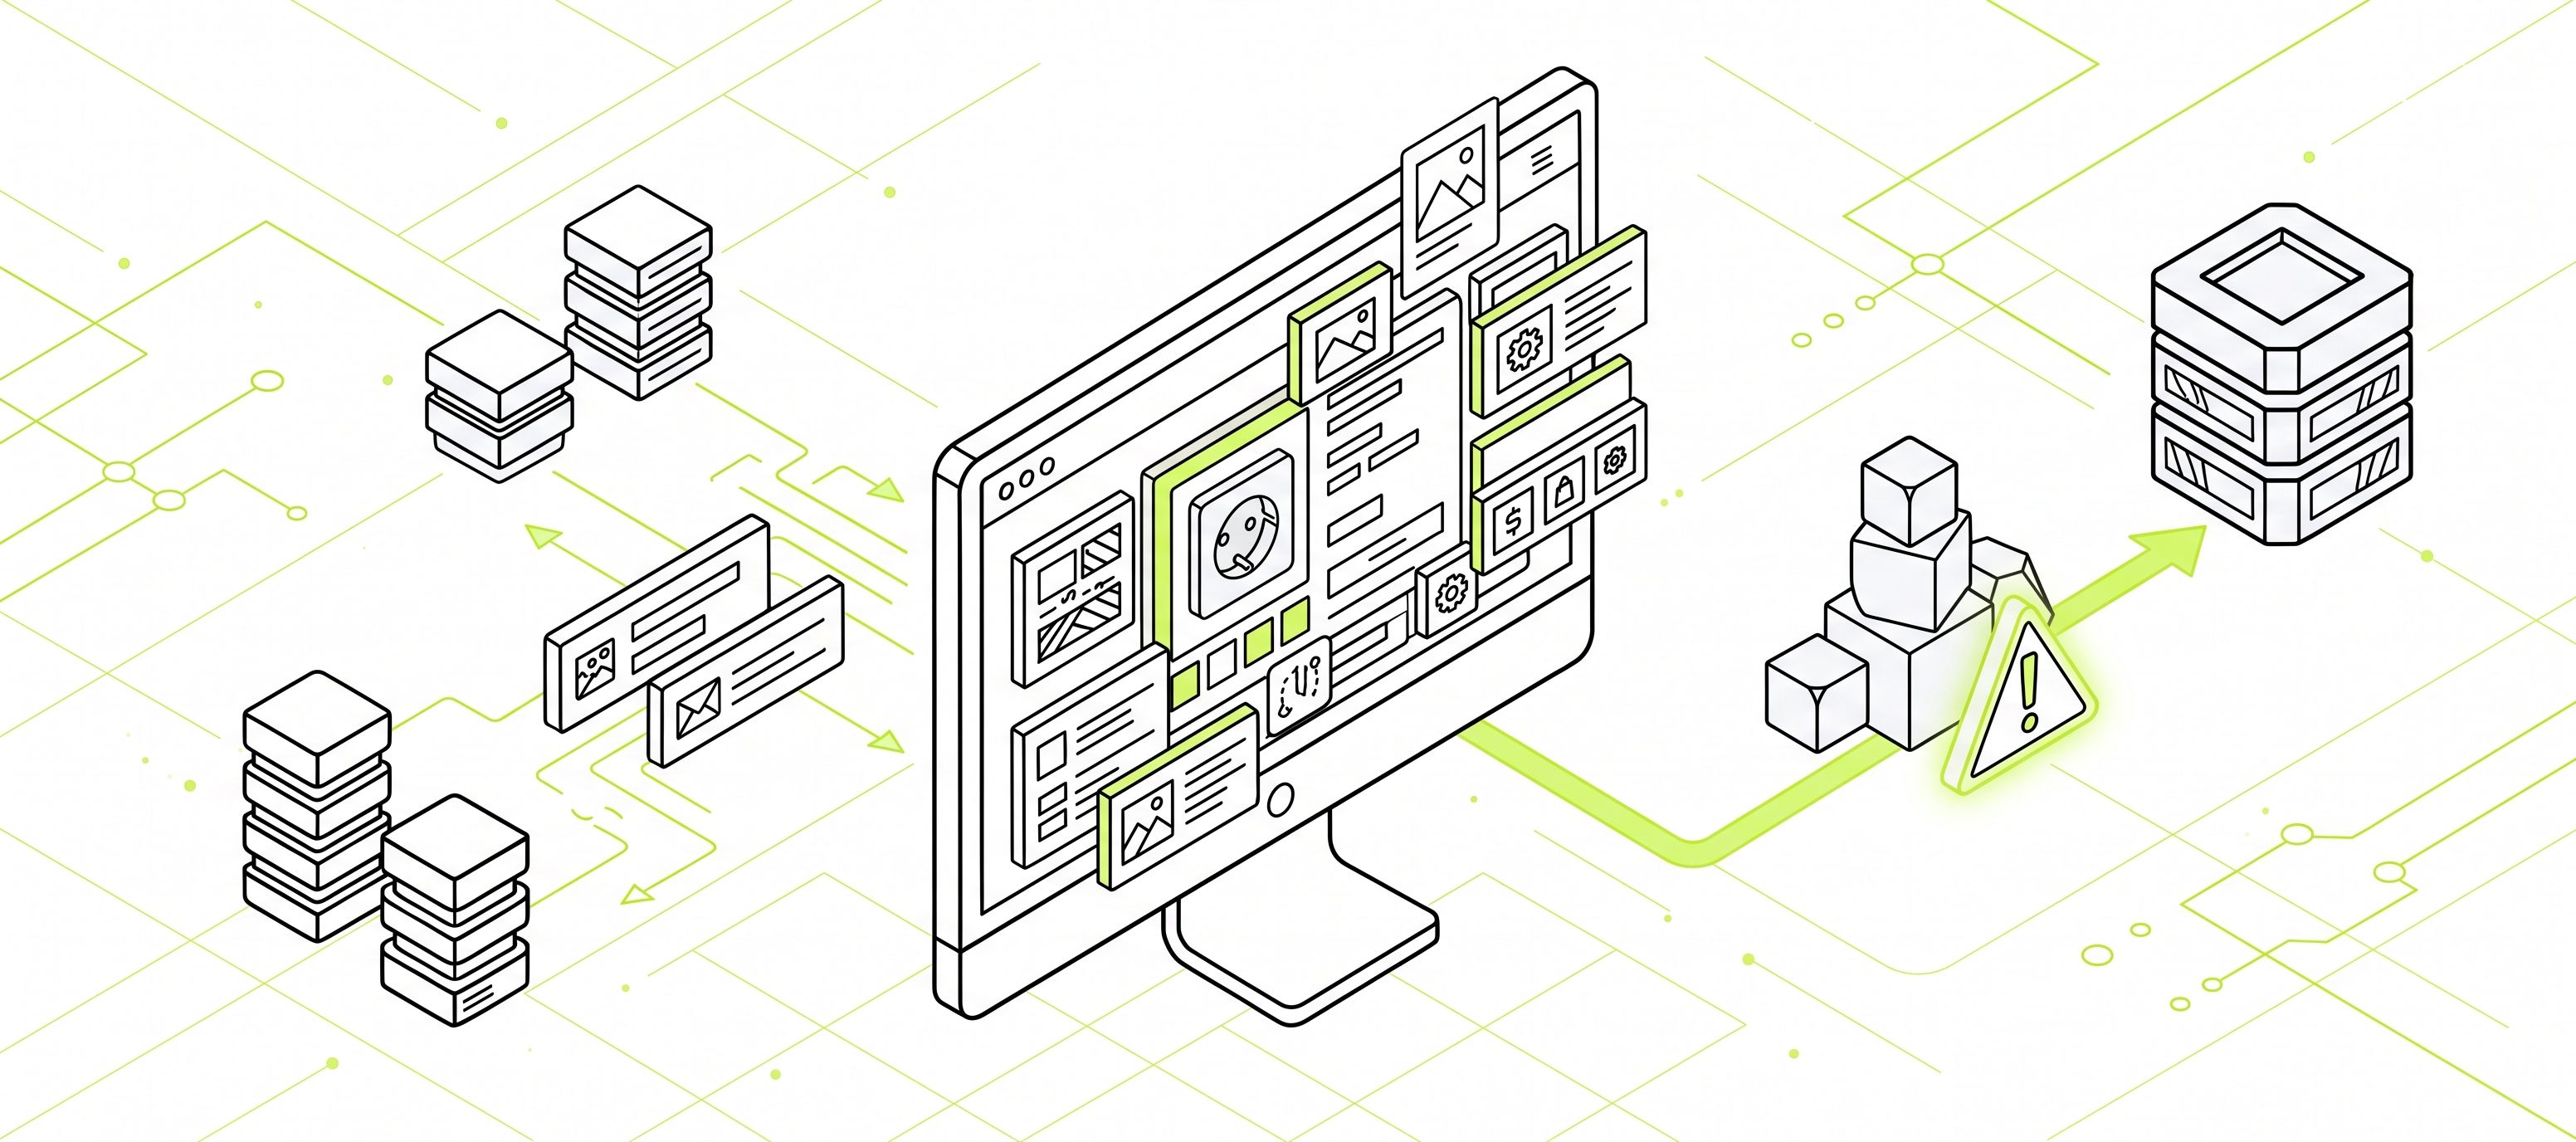
When product imports go wrong, the first suspicion falls on the tool. Poor file format, poor importer, API that's too slow. It seems like a technical issue—something that can be fixed with a better script and a single sprint.
This is almost never the case. In the projects we work on, implementation stops not at the technology, but at the product attributes. It's about the fact that a field described as "text" actually has a dictionary of two thousand values. That "height in centimeters" has twenty-one values to choose from, even though it should be an input field. That the same physical quantity is sometimes stored with a space, sometimes without—and the system treats them as two different things.
It's a debt that has been accumulating for years and which—and this is the interesting part—no one inside the company wants to touch.
Why hasn't anyone touched this for years?
Here is the crux.
The organization of attributes often doesn't belong to anyone in particular—there's no owner. The product department will say it's an IT topic—after all, it's a database. IT will say it's a product topic—because it's about substantive decisions, or "brushed gold" is a distinct color. E-commerce will say it's a thing of the past. Each of these answers is partially true, and that's why the topic lies.
The starting point for solving this problem isn't value cleansing or tool selection, but rather separating who is responsible for what in the process: who decides whether "brushed gold" is a new color or a variant of an existing one, who enters this decision into the system, and who ensures the catalog doesn't diverge during subsequent imports. Unless these three roles are assigned, every conversation about organizing attributes ends the same way: no one starts because no one feels responsible. In practice, we see this every time a client begins organizing product data, regardless of the industry or catalog size.
Then there's the cost-benefit asymmetry. Clearing out two thousand values takes weeks of tedious work, the results of which are invisible—the store looks the same afterward. Unless there's a project that compels this, there's no reason to start. And when a project does arise—PIM implementation, migration, import automation—it turns out that this very debt is the rock on which everything falls apart. And suddenly, it has to be repaid in a week.
Honestly: we won't clean this up for the client either. The decision of whether "brushed gold" maps to "gold" or becomes a separate value is a business decision, not a technical one. The implementer can prepare it, describe the consequences, and automate its execution—but they can't actually make it.
How to check in fifteen minutes if the problem concerns you
You don't need an audit to diagnose this. Simply export a list of attributes from the system, along with the number of values for each, and look for extreme cases. The sheer number of values is a telltale sign—if an attribute has hundreds or thousands of them, it almost always means one of three things:
- Wrong field type. Continuous quantity (height, weight, power) stored as a picklist instead of a numeric field. Each new product adds a value to the dictionary.
- No record normalization. The same value with a space, without a space, with and without a unit. To the system, these are separate entities; to the front-end client, they are three identical entries in the filter.
- No mapping rule. Data from different manufacturers falls into the same field without translation into the internal dictionary.
The second step, even simpler: enter a specific attribute and count how many times each value actually appears. Values used once or twice are usually typos and duplicates. This is a list to clean up—and also evidence that can help the company get things moving, because it shows the scale in numbers, not in complaints.
Organizing doesn't have to be a huge project
The most common mistake is treating it as a one-time, "clean everything up" effort. This fails because the scope is daunting and the impact is delayed.
What works better:
- Establish responsibilities before anyone starts cleaning data. Who decides whether "brushed gold" is a new color or a variant of an existing one (product), who enters this decision into the system (implementation specialist or IT department) and who makes sure that new data from manufacturers does not disturb the established order (e-commerce or the data department). It doesn't have to be one full-time position, but it must be clear who is responsible for each of these three decisions - without this, every cleaning job falls apart at the next import.
- Start with the attributes that are actually used — in filters, in search, in feeds. The rest can wait.
- Instead of cleaning, map. Establish a rule once ("convert every instance of 'brushed gold' to 'gold'") and save it in the tool so it works with every subsequent import. Most companies don't have such a tool yet, and this is precisely the element worth building, because otherwise, every rule will start to get lost with subsequent imports. Cleaning that doesn't solidify the rule needs to be repeated every quarter.
- Arm the process with input-side validationso that data from the manufacturer does not add new values without human decision.
And something that sounds trivial but is usually decisive: data organization should begin before implementation, not during it. Then it becomes a planned effort. During implementation, it becomes a crisis with a deadline.
What is the conclusion?
If you are planning a PIM implementation , migration, or import automation, check three things before choosing a tool:
- Do you have a separation of who decides on attribute values, who enters these decisions into the system, and who is responsible for ensuring that new data from producers does not disrupt the established order?
- How many values do your most complex attributes have—and do their type match what they actually describe?
- Is there a rule for mapping data from producers to your dictionary, or are each imports ad hoc decisions?
The first question is the most difficult and important. Technology can handle the mess, the scale of which you know. It can't handle the fact that no one wants to touch it.